JoMoHa: How Should We Optimize Model Weights and the Harness Together?
TL;DR
Train the model and its harness on the same task attempt.
Taking turns can make the two less compatible. JoMoHa jointly trains the harness writer and the task Solver with reinforcement learning, using two critics that account for how the pair worked together.
- ALFWorld success
- 97.0%
- Across three benchmarks
- 70.3% average
What goes wrong when we alternate?
The sponge was already clean. All the Solver had to do was put it on a cart. But the harness, the code that tracks progress and guides the model through the task, had missed the update. It kept sending the Solver back to clean the sponge. The run hit the 50-turn limit. Take the harness away and the same Solver finished in 14 turns.
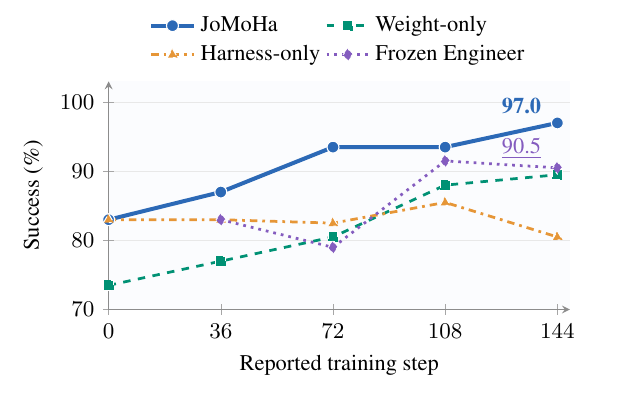
That was one failure in a long-phase alternating run on ALFWorld. We trained the Solver with the harness fixed, then trained the harness writer with the Solver fixed. Success initially rose from 83.0% to 90.5%, then fell to 31.5% as training continued.
Was this just a bad harness? We tested earlier and later Solver checkpoints with and without the same learned harness. The old harness interfered more with the later Solver, but the later Solver also did worse on its own. This is what makes training the two components hard to separate: the harness influences not only how the model acts, but also what it experiences during training.
What should the two policies learn from each other?
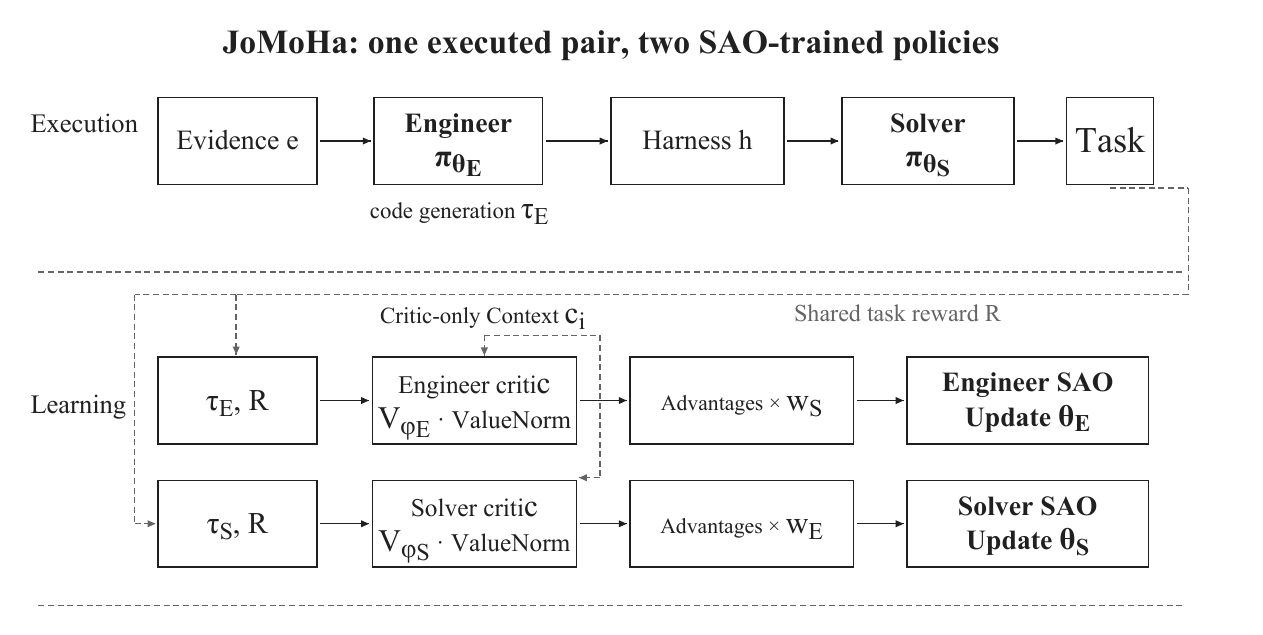
To our knowledge, JoMoHa is the first reinforcement-learning framework to jointly train a policy that writes executable harnesses and a policy that acts under them. The Engineer learns to write harnesses for the Solver it actually worked with, and the Solver learns from acting under the code the Engineer actually wrote. The harness writer itself learns from execution feedback rather than staying fixed.
The subtle part is choosing what to compare that reward against. Back to the sponge: a failed run tells us the pair didn’t finish. It doesn’t tell us whether the Engineer wrote unhelpful code or the Solver made a poor choice despite good guidance. We give each policy its own critic. Each estimates a baseline using the policy’s own history plus a short summary of the task, training version, and execution conditions. The critics don’t share weights, and the extra context doesn’t go to the policies. What they share is the task attempt: each can ask whether its outcome was better or worse than expected given the conditions under which the pair worked.
The other design choices address different parts of the same training problem. Separate return normalization accounts for the different scales of writing one program and acting over many turns. Partner-trajectory weighting adjusts how much a recorded attempt influences an update as the other policy changes. Extra Solver updates give it time to adapt to sampled harnesses without another change to the Engineer’s weights.
Does coordination improve the pair?
On ALFWorld, joint training without those four mechanisms reached 88.5%. Adding critic context alone brought it to 92.5%, the largest gain among the individual additions. The full method reached 97.0%.
We also tested whether the learned harness itself got better, not just the Solver. With the later Solver’s weights held fixed, swapping the initial harness for the later one raised success from 92.5% to 96.5% in the cross-checkpoint evaluation. In the main comparison, JoMoHa led the evaluated methods on ALFWorld, WebShop, and DBBench, averaging 70.3%, 7.2 percentage points above WHALE.
Joint work with Guangchen Lan, Mingqi Yuan, and Jiayu Chen. Figures 1 and 3 are reproduced from the JoMoHa paper under CC BY 4.0.